
The Real Cost of Model Migration - What Swapping LLMs Actually Requires
Model deprecations are routine. What they expose underneath - unmeasured quality, model-coupled prompts, unversioned behavior - rarely is. This post walks...
Model deprecations are routine. What they expose underneath - unmeasured quality, model-coupled prompts, unversioned behavior - rarely is. This post walks...

A RAG system can give a different answer today than last week, with the same model and the same prompt - because the index changed. Retrieval drift is...
"A tutorial on evaluating a minimal LangChain RAG pipeline with RAGAS metrics in MLflow: golden dataset, Faithfulness, Context Precision, Context Recall and...
Shape Up replaces two-week sprints with six-week cycles, kills the backlog, and lets small teams decide how to build things. Here is when it works, when it...
How to use GitHub Copilot to build test suites around behavior rather than coverage percentages: behavioral auditing, API contract tests, generating...
In-memory options for small knowledge graphs instead of a full graph database: NetworkX, RDFLib, PyGraphviz and a custom Python structure, with guidance on...
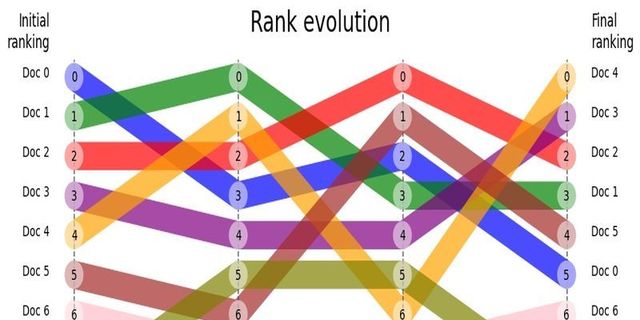
How to collect document rankings from each re-ranking step of a RAG retriever, using structured logs or callbacks, and visualize rank changes with a rank...
What LLM observability is, which functions an observability solution should provide, and a list of open source tools such as Langfuse, Phoenix, OpenLLMetry,...
What prompt discovery is: a systematic process for finding and refining prompts that get the desired output from a language model, weighing response...
Techniques to improve RAG performance in production, including hybrid search, chunk summaries, query transformations, embedding fine-tuning, re-ranking,...