
The Real Cost of Model Migration - What Swapping LLMs Actually Requires
Model deprecations are routine. What they expose underneath - unmeasured quality, model-coupled prompts, unversioned behavior - rarely is. This post walks...
Model deprecations are routine. What they expose underneath - unmeasured quality, model-coupled prompts, unversioned behavior - rarely is. This post walks...

AI-assisted engineering keeps operational control (approve, reject, sign off) but erodes epistemic control (understanding what was built and why). How...

A RAG system can give a different answer today than last week, with the same model and the same prompt - because the index changed. Retrieval drift is...
"A tutorial on evaluating a minimal LangChain RAG pipeline with RAGAS metrics in MLflow: golden dataset, Faithfulness, Context Precision, Context Recall and...
Shape Up replaces two-week sprints with six-week cycles, kills the backlog, and lets small teams decide how to build things. Here is when it works, when it...
This article explores how to move beyond simplistic code coverage metrics to build truly comprehensive test suites using GitHub Copilot. Drawing from...
As developers, we often reach for full-scale graph databases when simpler solutions would suffice. When your knowledge graph is modest in size, keeping it...
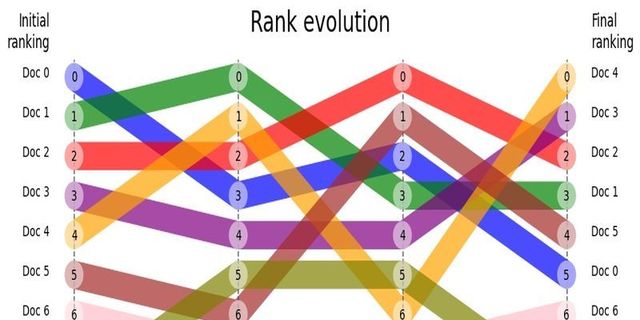
RAG systems depend on high-quality retrieval to surface relevant information. Analyzing how document rankings evolve through multiple re-ranking steps is...
Managing and monitoring the complex behavior of Large Language Models (LLMs) becomes increasingly crucial. LLMOps and LLM Observability provide essential...
Learn prompt discovery to uncover the most effective prompts and combinations thereof to achieve specific tasks, while also considering factors like...